11 What AI costs the planet: the number everyone quotes
About 60 minutes
- The idea. “A bottle of water per email” and “five drops per prompt” are both real figures. They differ about two-thousandfold because they counted different things. You can trace a figure to its source and say what it counted.
- What you do. Ask ChatGPT Edu to find the sources behind the two figures and say what each counted, then open one source and check it.
- What you keep. One sentence each for the resident and the medical director, and one question for a vendor that has a checkable answer.
- Short on time? Read “Where the bottle came from” and “What each of them counted”. Do Part A.
By the end of this chapter you will be able to:
- Trace a widely quoted figure about AI’s environmental cost back to the paper or report it came from, and say what changed at each step on the way to you.
- Name three choices that make credible per-query figures (the cost of one question to a chatbot) differ by more than a hundredfold, and say which choices the figure you traced made.
- Put AI’s per-query cost against your own specialty’s measured footprint, and say what that comparison settles and what it does not.
- Explain how a per-query number can shrink thirtyfold in a year while the total keeps rising, and name who lives next to the data centers that make up the total.
- Ask a vendor one question about their environmental figure that has a checkable answer.
Course competencies: AIM-3 (bias and equity), AIM-2 (critical appraisal), AIM-7 (workflow and systems).
What you need. Your university ChatGPT Edu or Copilot account, a browser, and a calculator. Nothing to install. Nothing in this chapter involves a patient. The time counts about 18 minutes of reading, the 11-minute talk, and about 25 minutes of doing; Part B and Go deeper are optional.
11.1 Morning huddle
It is the first week of your family medicine rotation, in a county that spent the summer under outdoor watering restrictions. The clinic is rolling out an ambient scribe, the phone app that listens to the visit and drafts the note. At huddle, a second-year resident says she is opting out. She has read that every note the thing writes costs a bottle of water, and she is not going to pour out a bottle of water per patient in a drought. The medical director, who signed the contract, says that is nonsense. He read last month that a prompt, one message to a chatbot, uses about five drops. They look at each other, then at you, because you are the student, and students get asked to look things up. Find out by Friday, he says. Which is it?
Both of them are quoting something real. The bottle traces back to a paper and a newspaper analysis. The five drops trace back to a technical report from the company that runs the model. The two figures differ by a factor of about two thousand. Neither person has read past the headline. Neither, until Friday, have you.
This is a common problem with numbers in medicine: a number that arrives without its method. Numbers about the planet are often repeated and rarely checked. The question to ask is the same as for any cited number: what did they count, and did anyone check?
11.2 Why this matters
The figure on the infographic is not about your clinic. It is a claim about what happens somewhere else, to someone else, when you press enter. That makes it a question of fairness, not only a question of adding up carbon. Water and air pollution are local. A data center’s cooling draws from one county’s groundwater. A gas turbine’s exhaust lands in one neighborhood. The people who bear that cost do not use the tool and were not asked. That is the course’s fourth recurring lesson, who benefits, who bears the risk, who decides, explained in the ethics chapter. In the emergency department of that neighborhood, an asthma exacerbation is an asthma exacerbation. No one can say what caused it, and you would treat it the same. This chapter is about being able to say, honestly and in proportion, what the tool on your workstation has to do with that.
You will meet the practical version sooner. Within a year someone on your team will refuse a tool on environmental grounds, or dismiss the concern outright. Both will be quoting a headline. Within a few years you may sit on the committee that picks the vendor, and “what is its footprint” will be a line on the purchasing form. The skill that lasts is not a number to quote. The numbers in this chapter will be wrong within eighteen months, and the chapter says so. The skill is asking what was counted.
11.3 How it works
11.3.1 Where the bottle came from
Start with the resident’s bottle and trace it back to its source. Every step is public. You will do this yourself in the Do block, so read this as the worked example.
April 2023. A group at the University of California, Riverside and the University of Texas at Arlington posted a preprint, a paper shared before peer review, titled “Making AI Less Thirsty.” It was published two years later in Communications of the ACM (Li et al., 2025). But the first arXiv version contains the sentence the whole story came from: ChatGPT needs to “drink” a 500 mL bottle of water for a simple conversation of roughly 20 to 50 questions and answers, depending on when and where it runs. Read that carefully. It is a bottle per conversation, not per question: 10 to 25 mL per question. It is an estimate for GPT-3, the model behind the first ChatGPT. It rests on an assumed energy cost of 0.004 kWh per request, which the authors called conservative. And it counts two kinds of water: the water evaporated on site to cool the servers, and the water evaporated off site by the power plants that make the electricity. In the United States the power-plant share is the larger one. The paper’s most quoted number, 700,000 litres to train GPT-3, is about training, not use. The current version of the paper gives the per-response figure as a bottle per 10 to 50 medium-length responses.
September 2024. The Washington Post worked with the same Riverside group on a new estimate. A 100-word email written by GPT-4, it reported, uses 519 mL of water and 0.14 kWh of electricity in a typical US data center. The headline was “A bottle of water per email.” Notice what has changed since the preprint: a much larger model, a specific task rather than a “simple” question, and a number roughly twenty to fifty times larger per interaction. The resident’s bottle is this headline, with “per email” changed to “per note” by a year of repetition.
August 2025. Google published a technical report on what a median Gemini text prompt costs on its own computers: 0.24 Wh of energy, 0.03 grams of CO2e, and 0.26 mL of water. A watt-hour (Wh) is what a one-watt LED uses in an hour; a kilowatt-hour (kWh) is a thousand of them. CO2e is carbon dioxide equivalent, the unit that expresses every greenhouse gas as one number. Google’s blog post described the water as “about five drops” (arXiv 2508.15734; Google Cloud blog, 21 August 2025). The energy figure is unusually complete. It includes idle machines, the host computer, and the building’s cooling and power overhead. The report says that over the previous twelve months the energy per prompt fell 33-fold and the carbon 44-fold. The water figure is not complete in the same way. It counts on-site cooling water only, not the water used by the power plants. The Riverside group said so within a day. They pointed out that Google had compared its on-site figure to their on-site-plus-off-site figure and called the difference “orders of magnitude,” meaning several tenfold steps. The medical director’s five drops are this report, with the word “on-site” left out.
Three headlines, three kinds of source: a newspaper working with academics, a vendor reporting on itself, and trade press reporting the academics’ objection to the vendor. Every one of them is about a real number. The resident read the first. The medical director read the second. The honest answer needs the third.
11.3.2 What each of them counted
Put the sources side by side and the disagreement stops looking like a dispute about facts.
| Source | Date | Model | Unit | Water counted | Energy per unit | Water per unit |
|---|---|---|---|---|---|---|
| Li et al., preprint | Apr 2023 | GPT-3 | one Q&A in a “simple conversation” | on-site + off-site | 4 Wh (assumed) | 10–25 mL |
| Washington Post with UC Riverside | Sep 2024 | GPT-4 | one 100-word email | on-site + off-site | 140 Wh | 519 mL |
| Altman, personal blog | Jun 2025 | ChatGPT, “average” | one query, undefined | not stated | 0.34 Wh | 0.32 mL |
| Google, technical report | Aug 2025 | Gemini Apps, median text prompt | one prompt | on-site only | 0.24 Wh | 0.26 mL |
Three things can be wrong with a cited claim. The reference: does the source exist? The attribution: does the source say what it is quoted as saying? And the claim itself: is it true? Apply the three to the bottle. The reference is fine: the preprint exists, the newspaper analysis exists. The attribution is where it failed. A bottle per 20 to 50 questions became a bottle per email, which became a bottle per note, and none of those is what the source said. The claim, whether AI use is a meaningful water cost, is a different question from either. It is the one no per-query figure can answer alone.
11.3.3 Three choices that move the number a hundredfold
Figure 11.1 puts every per-query figure in this chapter on one chart. The spread is not error. It is three decisions. Each is reasonable, and each changes the answer tenfold or more.
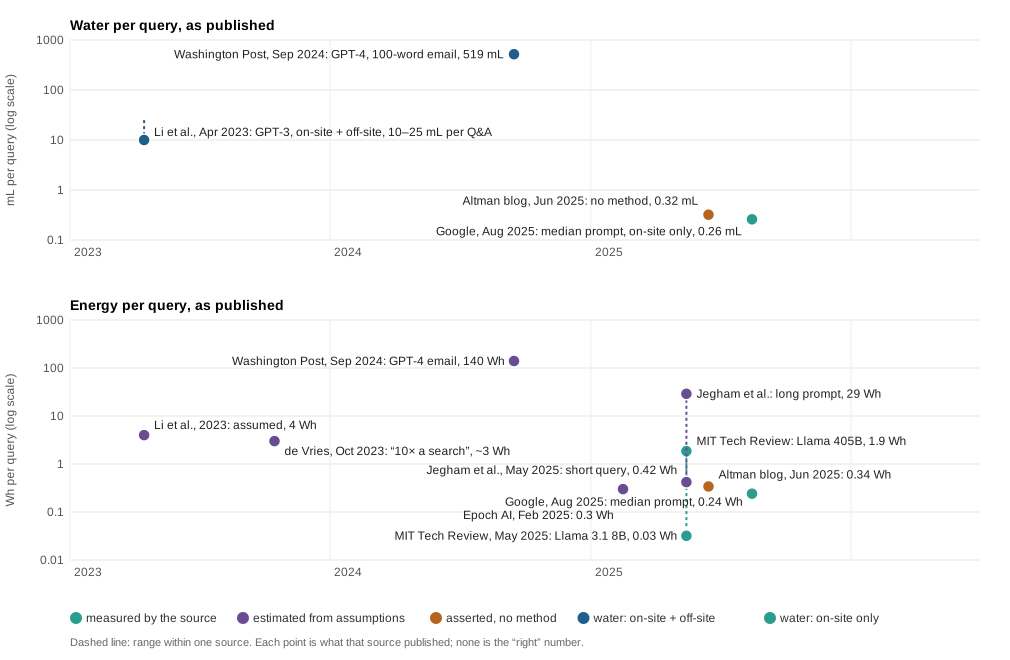
What you count. For water: on-site cooling only, or the power plant’s water too. For energy: the chip while it is computing, or the chip plus everything around it. That means the idle machines waiting for the next request, the host computer, and the building’s cooling and power losses, a multiplier the industry calls PUE, power usage effectiveness. Then there is training. The one-time cost of training the model can be spread across every query it will ever answer (the accounting word is amortized), or left out because it already happened. Google’s energy number counts all of this. Its water number does not. Li et al. counted both kinds of water but assumed the energy. Nobody in Table 11.1 is lying. They are answering different questions.
Which query. A long prompt, a 100-word email, or a “reasoning” setting costs far more than a short question. An independent test of thirty commercial models found short queries near 0.42 Wh. The models that used the most energy went above 29 Wh for a long prompt (Jegham et al., arXiv 2505.09598, May 2025).
Which model, and when. On the same hardware, the largest open model that MIT Technology Review had measured used about sixty times the energy per response of the smallest (O’Donnell and Crownhart, 20 May 2025). Google’s 33-fold drop in twelve months is the same kind of spread, produced by time instead of size. A figure without a model and a date is not a figure.
Every figure in this chapter carries a date, because every one of them will be replaced by a newer one. The “10 times a Google search” line that opens most articles on this topic traces to a 2023 commentary in Joule (Vries, 2023). It compared an estimate for a language model against a Google figure for search energy published in 2009. Real journal, real author, repeated everywhere, and the comparison was fourteen years out of date on the day it was made. Independent re-estimates in 2025 settled near 0.3 Wh for a typical text query, about a tenth of the number that commentary made famous (Epoch AI, February 2025). When you meet a per-query number, the first question is not whether it is right. It is which year and which model it belongs to.
11.3.4 Small per query, large in total
Take the most favorable documented figure and do the arithmetic this chapter depends on. Forty-nine students, fifteen queries a week, four weeks: 2,940 queries. At Google’s 0.24 Wh that is about 0.71 kWh, a microwave running for about forty minutes. At 0.26 mL it is about 760 mL of on-site water, a bottle and a half, for the whole class for the whole month. At 0.03 g CO2e a query it is about 88 g. Compare that with US health care’s own measured footprint: 1,692 kg CO2e per person per year in 2018, the highest of any industrialized nation, with 388,000 disability-adjusted life-years lost that year to the sector’s pollution (Eckelman et al., 2020). The class’s month of AI use is a few thousandths of one percent of one person’s share.
State the limit of that calculation, because you will be tempted to stop there. It uses the one per-query carbon figure a vendor has published, which is also the most favorable of the energy figures, and it counts on-site water only. At the Post’s 519 mL the class would have used about 1,500 litres. The honest sentence is this: at the best-documented rate, an individual’s use is negligible, and the published rates differ by about a thousandfold.
Then notice that the individual question is not the question. Google’s energy per prompt fell 33-fold in a year. Its total emissions went the other way. On its own reports, they were 48 percent above its 2019 level in 2023, 51 percent above in 2024, and 81 percent above in 2025 (ESG Dive, 2 July 2025; ESG Dive, 2 July 2026). Its data centers’ electricity use rose 37 percent in 2025 alone. This is the second of the course’s four recurring lessons, efficiency gains get eaten by volume. Economists call it the Jevons effect, after the observation in 1865 that more efficient steam engines led Britain to burn more coal, not less. When a unit of something gets cheaper, people use enough more of it that the total rises. Per-query efficiency is real, but use is growing faster. A US national laboratory projects that data centers will rise from 4.4 percent of US electricity in 2023 to 6.7 to 12 percent by 2028 (Berkeley Lab, December 2024).
The consequence for the resident is uncomfortable in both directions. Her opting out of the scribe changes nothing measurable. And the medical director’s five drops, multiplied by the volume that makes five drops possible, is the demand the turbines in the next section were installed to meet.
11.3.5 Where the cost lands

Carbon spreads. Whoever emits it, it warms everyone. Water and air do not spread in the same way. A data center’s cooling comes out of one county’s supply, and a gas turbine’s exhaust settles on one neighborhood. That is why this chapter counts as a fairness chapter as well as an environmental one.
About two-thirds of new data centers built or in development since 2022 are in places already under high water stress, meaning short of water, according to a Bloomberg News analysis (Bloomberg, May 2025).
In the Memphis area, the AI company xAI has powered its computers with gas turbines. At its first site, in South Memphis, turbines ran for about a year before the county approved an air permit in July 2025. That timeline comes from the environmental law group that represents local residents (SELC, May 2026). Its second site is just across the state line in Southaven, Mississippi. There, the state approved an air permit in March 2026, and community groups have appealed it. In April 2026 the NAACP sued xAI in federal court, alleging that turbines were running without the Clean Air Act permits they needed (Earthjustice case page). The case is in court. As of 12 October 2026 we found no ruling on the claims.
If people nearby develop asthma attacks, the emergency physician who sees them has no way to link the visit to the turbines. That is environmental exposure as a social determinant of health, in the form you were trained to recognize and can rarely act on.
One more piece of vocabulary, because it decides what a vendor’s number means. A company can report the emissions of the electricity it actually drew from the local electricity grid. That is called location-based accounting. Or it can report the emissions left after subtracting renewable power it bought on contract somewhere else. That is called market-based. Meta’s model card, the published fact sheet, for its Llama 3.1 models reports training at 11,390 tonnes CO2e location-based and zero market-based, in the same table (Meta model card). Both are accepted ways of counting. Only one of them tells the people in Memphis anything.
11.3.6 The denominator, and the claim not to repeat
A per-query number needs a denominator: something of your own to compare it against. Health care is not exempt from the same question. Its footprint is measured, large, and yours. The 1,692 kg per person figure above comes with a state-by-state analysis. Emissions were not closely correlated with the quality of care, which is the authors’ argument that the sector could cut them without harming care (Eckelman et al., 2020). A scoping review of the environmental footprint of digital health tools found no validated method for assessing one across its whole life cycle. Most studies simply estimated the travel that telehealth avoided (Lokmic-Tomkins et al., 2022). The literature on AI’s footprint in medicine is newer, and so far mostly opinion pieces rather than measurements; four are listed in Go deeper.
For a purchasing committee, one measured result matters more than the opinion pieces. A radiology group ran five sizes of two open models over 3,665 chest radiograph reports and metered the electricity. A 7-billion-parameter model (parameters are a measure of model size) matched the accuracy of a general-purpose model ten times its size. That smaller model was Vicuna, a version of Llama 2 further trained to hold general conversations, not trained on radiology. The largest general-purpose model used more than seven times the energy of its smallest version (Doo et al., 2024). The lesson is the one Figure 11.1 teaches, seen from the buyer’s side: which model you run changes the total more than whether you run one at all.
You will meet the sentence “autonomous AI could cut health care’s emissions by 80 percent.” It comes from a real, published estimate. It compared the greenhouse-gas cost of one autonomous diabetic-retinopathy screening visit with one in-person specialist visit, and found the AI visit about 80 percent lower (Wolf et al., 2022). Three of its six authors list the company that makes the screening device as an affiliation. That does not make it wrong, but it is the same kind of source as Google’s report: a company estimating the cost of its own product. And it is a finding about one screening test replacing one kind of visit, not a measurement of health care as a whole. If you repeat it as a general claim you have made the attribution error from Table 11.1, in the optimistic direction. The bottle and the 80 percent are the same mistake: one makes AI look worse than its source says, the other makes it look better.
11.4 Watch or listen
Video. Sasha Luccioni, AI is dangerous, but not for the reasons you think, TEDWomen, October 2023 (11 min; transcript and subtitles on the TED page). https://www.ted.com/talks/sasha_luccioni_ai_is_dangerous_but_not_for_the_reasons_you_think Also as a podcast episode, TED Talks Daily, 31 October 2023, 11 min.
Luccioni led the team that measured the training footprint of BLOOM, one of the few large models whose energy and carbon were published in full. She also built the public leaderboard that rates models’ energy use on standard tasks. Listen for what she says she counted when she measured a model, and for the date: the talk comes before every 2025 figure in Figure 11.1. Then ask whether anything she says about carbon has since become less true, or only smaller per query. The eleven minutes cover copyright and bias as well; the environmental section is the first third.
Reading alternative. MIT Technology Review, “We did the math on AI’s energy footprint” (O’Donnell and Crownhart, 20 May 2025). Read it after the guessing exercise in the Do block, not before. If you read it first, skip step 1 of Part A; the point of step 1 is to guess before you know.
11.5 Do
Made-up patients only. What counts as patient information.
11.5.1 Part A: trace the bottle with ChatGPT (20 minutes)
Step 1. Guess. Before opening anything, write down your own guess for the water one chatbot question uses, in millilitres.
Step 2. Ask. In ChatGPT Edu (Copilot also works), paste this:
Two figures circulate for the water a chatbot uses: "a bottle of water
per email" and "about five drops per prompt". Find the original source
of each, and the 2023 UC Riverside preprint "Making AI Less Thirsty".
For each of the three sources, give the date, the model, the unit (per
what), which water was counted (on-site cooling only, or power-plant
water too), the number, and a link.
It will probably find most of this. Copy its answers into the table.
Source        Date     Model     Unit ("per ___")     Water counted        Number
Preprint      ______   ______    ________________     _______________      ______
Post          ______   ______    ________________     _______________      ______
Google        ______   ______    ________________     _______________      ______
Step 3. Check one row. Ask, then check: most of a good answer is right, and your job is to find out which parts. Open one source yourself, from the chatbot’s link or from these:
- The preprint, first version: arxiv.org/abs/2304.03271v1. Open the PDF and search for “500ml”.
- Google’s report: arxiv.org/abs/2508.15734. Search for “water” and find the sentence that says what the water figure includes.
- The Post analysis, or if it is paywalled for you, the TechRepublic summary of it: techrepublic.com.
Mark each cell in that row as confirmed or corrected. It may get every cell right. If so, you know because you read the source yourself.
Step 4. Make them comparable. Convert each to millilitres per single question. The preprint gives a bottle per 20 to 50 questions; divide. The Post gives one email; decide, and say, whether you treat that as one question. Google gives one prompt. Then compute the ratio of the largest to the smallest.
Preprint, per question:  ______ to ______ mL
Post, per question:      ______ mL   (I treated one email as ___ question(s))
Google, per prompt:      ______ mL   (on-site only)
Ratio, largest/smallest: ______

The single choice that explains most of the ratio is: ________________
Step 5. The verdict, in one sentence each. Write what you will say to the resident and what you will say to the medical director. Each sentence must name the source’s date, model, and what it counted. “It’s complicated” is not a sentence.
11.5.2 Part B (optional): your specialty’s denominator (10 minutes)
The per-query number means nothing without something of yours to put it against. Find your own specialty’s measured footprint. In PubMed:
("carbon footprint" OR "greenhouse gas" OR "life cycle assessment")
AND <your specialty, or one procedure you will do a lot of>
Filter to the last five years. Skim titles for one paper that reports a number per encounter, per procedure, or per test: kilograms of CO2e per MRI, per laparoscopic cholecystectomy, per dialysis session, per telepsychiatry visit. Anesthesia, surgery, radiology, nephrology, and ophthalmology all have papers on this. If your specialty does not yet, use Eckelman’s 1,692 kg per person per year (Eckelman et al., 2020) and divide by a plausible number of encounters.
Paper: __________________________________   PMID: ____________
Unit: one _______________   Footprint: ______ kg CO2e

At Google's 0.03 g per prompt, one of my units equals ______ prompts.
At the highest energy figure in the chapter (29 Wh, Jegham et al.), using
Google's own ratio of 0.03 g per 0.24 Wh (about 0.125 g per Wh, so about
3.6 g per long prompt), it equals ______ prompts.

The sentence I would actually say: ___________________________________
The two prompt counts will differ a hundredfold and both will be large. That is the result. What it settles is that your own use does not decide the total. What it does not settle is the total, which is a different question and was never yours to answer alone.
11.5.3 Part C: one question and one rule (5 minutes)
The vendor question. Nobody has published a measured figure for an ambient scribe. The way to get one is to ask. Write one question you would put to the scribe vendor at the next contract review, one that has a checkable answer. The three that matter most are these. Does the reported footprint use location-based or market-based accounting? Where is inference physically hosted, and how carbon-heavy and water-short is the grid there? (Inference is the running of a trained model to answer requests, as opposed to training it.) Does the per-note figure include the training cost spread across queries, idle capacity, and cooling? A good fourth is whether they will publish a standardized energy score for the model they run.
One rule and one non-change. Write one practice you will actually keep, and one thing you considered changing and decided was not worth it, with the reason. A student who writes “I will keep using a model for literature search because my footprint is negligible against the clinical benefit, and the decision that matters is purchasing, not my own use” has done the reasoning this chapter asks for. So has the one who writes the opposite, if the reason is as specific.
Your rule and your non-change can go straight into your week 4 piece, “what you will keep” (see the learning journal).
11.6 Check
Score yourself before moving on.
| You have | Meets | Falls short |
|---|---|---|
| A traced chain (Part A) | Three rows, each with a date, a model, a unit, and which water was counted, and one row you checked against the source itself | “The Post said a bottle”, or rows copied without opening any source |
| A ratio and its explanation (Part A) | The ratio is computed, and the single choice that explains most of it is named | “They just disagree” |
| Two verdict sentences (Part A) | Each names a date, a model, and what was counted; each could be said aloud at huddle | “It depends” |
| Three choices (objective 2) | On-site versus total water; which query; which model and year, or equivalents, in your own words | Fewer than three, or “methodology” |
| A denominator (optional Part B) | A real paper, a real unit, an arithmetic comparison, and a sentence that says what it settles and what it does not | A comparison with no source, or one that concludes “so it doesn’t matter” |
| The Jevons sentence (objective 4) | You can say how per-query cost fell and total rose in the same year, with a source and date, and name who lives near the data centers that make up the total | “Efficiency is improving” |
| The vendor question (Part C) | Has a checkable answer; you can say what a bad answer would look like | “Is it sustainable?” |
| The rule and the non-change (Part C) | Both are specific and the reason is the arithmetic, not the mood | A rule with no reason, or no non-change |
11.7 What this changes for you
What does this change about how you’ll practice? Write it down before you close this chapter. Then go back to Friday’s huddle. The resident is still opting out and the medical director is still certain. You have three sources open and a ratio of about two thousand. What do you say to each of them, in one sentence each? And what do you say about the county’s water that is true at every point on Figure 11.1? Then the harder one. The scribe will be recording your patients either way. Whether they are told belongs to the patient-communication chapter, not to a water figure. Does what you learned this week change whether you use it? If not, what would?
11.8 Go deeper
Papers
- The water paper in its published form (Li et al., 2025), and the first arXiv version for the sentence the story came from.
- Google’s per-prompt method, arXiv 2508.15734, and the Register piece above for the on-site objection.
- The 2023 Joule commentary the “10× a search” line comes from (Vries, 2023); read it against the 2025 Epoch AI re-estimate to see how a number goes out of date.
- Luccioni, Jernite, and Strubell, “Power Hungry Processing” (arXiv 2311.16863, 2023): the first systematic comparison of the cost of running models, task by task, and the finding that general-purpose models cost orders of magnitude more per task than small specialized ones. The radiology study (Doo et al., 2024) found a similar pattern on chest radiograph reports.
- US health care’s footprint (Eckelman et al., 2020); the scoping review of digital-health footprints (Lokmic-Tomkins et al., 2022); and a 2026 systematic review of “green AI” in health applications, which argues AI can add to the footprint and reduce it (Alzoubi & Mishra, 2026).
- The health-specific perspectives: NEJM Catalyst (Osmanlliu et al., 2025), Lancet Digital Health (Selvan, 2026), Nature Reviews Nephrology (Schmitz et al., 2026), Lancet Global Health (Fiske et al., 2025).
- The retinopathy paper the 80 percent comes from (Wolf et al., 2022), to see what a careful single-use-case estimate looks like before it is generalized.
Explainers and tools
- MIT Technology Review, We did the math on AI’s energy footprint (20 May 2025), and Hannah Ritchie’s running estimate (updated August 2025), which is the closest thing to an answer that is kept up to date.
- Hugging Face AI Energy Score leaderboard: models rated on standard tasks on identical hardware, free to browse. If a vendor’s model is not on it, ask why.
- Electricity Maps: how carbon-heavy the electricity is in each region, updated live. Open it and find where your vendor hosts; where a model runs matters as much as which one.
Talks
- Machine learning fairness: the fairness vocabulary behind “Where the cost lands” (procedural, distributive, and representational fairness), and the two opening thought experiments that this chapter’s guess-first-then-check exercise borrows from. It is the bias and equity chapter’s reading alternative.